
Compute Chips
ASIC vs. GPU in 2026: Broadcom’s Custom Silicon Order Book Reveals the Shift
The AI chip market is becoming more diverse, not simply replacing one processor with another. GPUs remain valuable for programmable computing, while large customers increasingly commission custom accelerators that reflect their own workloads, infrastructure, and economics.
OpenAI’s Custom Chip with TSMC: The First Major LLM Company Going Silicon
OpenAI is moving deeper into the hardware beneath its models. Instead of relying exclusively on processors designed for a broad market, it is helping create silicon around the workloads that power its own products. That is a significant change in responsibility: the company is no longer only a customer of computing infrastructure, but also a participant in defining it.
Inference Era Pricing: Why LPU Architecture Targets the Token Generation Bottleneck
The price of an AI response depends on more than how much arithmetic a chip can perform. It depends on how quickly the system accesses data, how efficiently it schedules requests, and whether the resulting answer arrives within the application’s time limit.
China’s TPU Breakthrough: How Zhonghao Xinying Filled the Pure TPU Architecture Gap
China’s AI chip industry is often discussed through GPUs and neural-processing units. Zhonghao Xinying offers another route: a processor designed around tensor computation, supported by its own instruction set and computing platform.
More Threads and Biren’s GPU Iteration Race: China’s General-Purpose AI Compute Path
China’s domestic AI hardware effort is not following one architectural route. Some companies emphasize specialized neural processors. Others are pursuing programmable GPUs that can support a broader mix of training, inference, and general computing workloads.
Nvidia’s $1 Trillion Revenue Target by 2027: Behind the AI Factory Transformation
Nvidia’s trillion-dollar ambition is not a forecast of $1 trillion in revenue during the single year 2027. It is a statement about the cumulative business opportunity associated with Blackwell and Vera Rubin through that period—and about the scale of infrastructure customers may need as AI moves into continuous operation.
Vera Rubin Platform Breakdown: 7 Chips, 5 Racks, and a 10x Inference Efficiency Leap
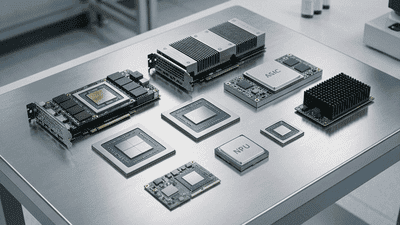
Nvidia’s Vera Rubin platform is easiest to understand as a coordinated AI infrastructure system, not simply a new GPU surrounded by accessories. Its components divide responsibility across computation, networking, storage, and orchestration so that fewer resources sit idle while another part of the system becomes a bottleneck.
Nvidia’s Groq 3 LPU: The Inference Coprocessor That Could Reshape AI Server Architecture
For years, the AI infrastructure conversation has revolved around a familiar question: how many GPUs can a data center deploy? Nvidia’s Groq 3 LPU suggests that the next question may be more interesting: which parts of an AI workload should actually run on those GPUs?
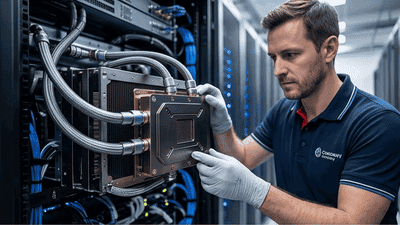
Liquid Cooling for 1000W+ AI Chips: The Infrastructure Bottleneck Nobody Priced In
The accelerator arrives. The server vendor has completed its work. The software team is ready to begin testing. Then the deployment stalls because the building cannot remove enough heat.
AI Chip Yield Challenges at 3nm: The Cost of Advanced Node Scaling
A smaller manufacturing node promises more computing capability within a constrained footprint. For AI chips, that can mean additional arithmetic units, improved energy efficiency, or room for functions that would be difficult to accommodate on an older process. The attraction is obvious. The economics are less automatic.